

I used to think of context the way I think about disk space. You have a limit, you fill it up, and once you’re close to full, something has to give, you summarize, you truncate, you start a new session. Bigger window, bigger budget, less often you have to deal with it. Simple.
That model is wrong, and it took a piece of research to convince me, not just a hunch. In July 2025, Chroma published a technical report that actually measured what happens to model performance as you feed it more tokens, across 18 frontier models, including GPT, Claude, and Gemini. The finding: accuracy doesn’t stay flat until you hit the limit and then fall off a cliff. It degrades steadily, well before that, dropping somewhere between 20 and 50 percent between 10,000 tokens and 100,000-plus, depending on the model and task. (Chroma, “Context Rot: How Increasing Input Tokens Impacts LLM Performance”)
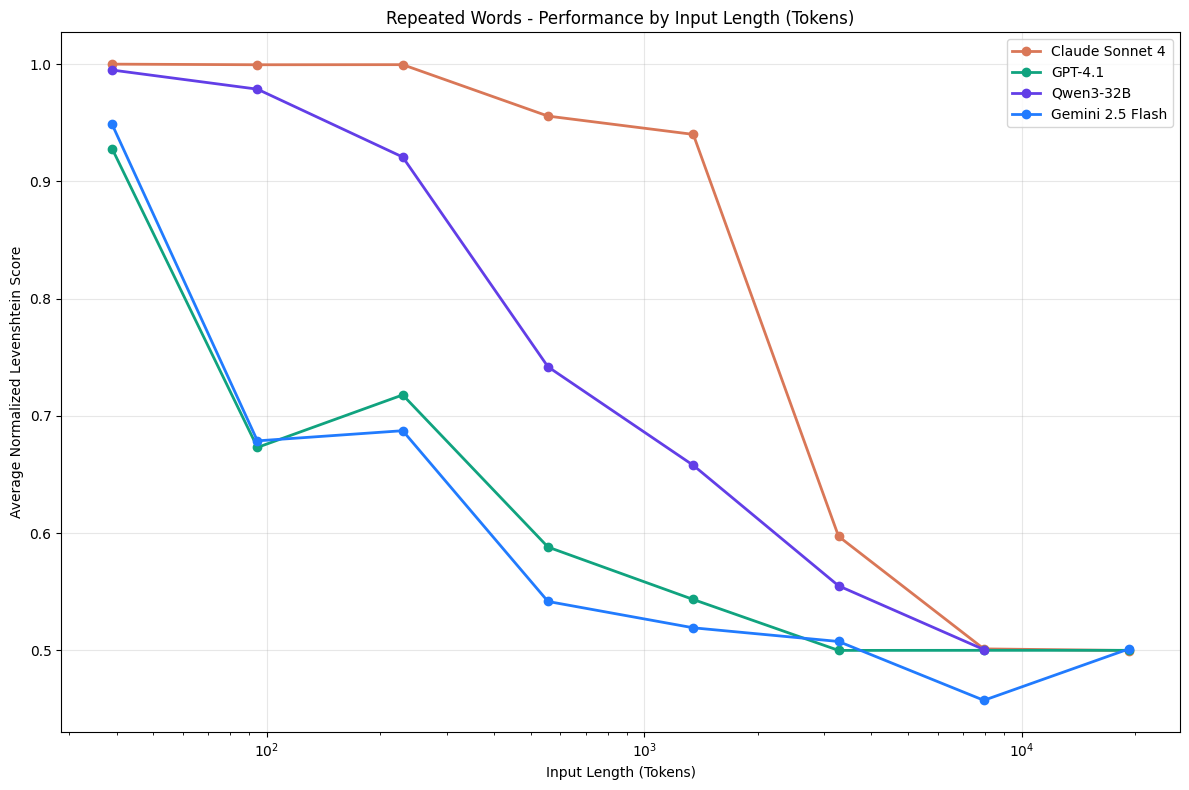
That’s not a capacity problem. A window sitting at 30 percent full can already be actively hurting the agent’s decisions.
This matters most exactly where this series has been focused: agents that don’t stop after one exchange. A chat session rarely accumulates enough tokens for any of this to bite, you ask, it answers, you’re done well under the range where degradation shows up. A long-running or always-on agent is a different animal entirely. It’s calling tools, reading their output, retrieving documents, reasoning about what it just did, over and over, for hours or days, and every one of those steps adds to the same window. It lives in exactly the token range where Chroma’s research shows performance quietly eroding, and it lives there for its entire run, not just a moment of it. A short session might never notice context rot exists. A long-running one is basically guaranteed to run into it, repeatedly, as a matter of course rather than an edge case.
What’s actually degrading
The part of the Chroma research that stuck with me most wasn’t the overall accuracy numbers, it was what specifically causes the drop. Two findings in particular:
Adding irrelevant but related information into the context sharply increases error rates, even when the model never needs that information to answer correctly. They call these distractors. A tool response that’s technically true but not needed for the current step, a document chunk that’s topically similar but not the right one, an earlier message that’s stale but still sitting in the window, all of these quietly degrade the model’s ability to reason about what actually matters, just by being present.
And it’s not only complex reasoning that suffers. Even basic tasks like copying a sequence of text verbatim start to fail as input length grows, with the model occasionally misplacing characters or just refusing the task outright. Models don’t fail gracefully here, they fail in ways that don’t look like “I’m confused,” they look like a wrong answer stated confidently.
For a short chat session, this barely registers, you’re nowhere near the range where it bites. For a long-running agent, accumulating tool outputs, retrieved documents, and its own prior reasoning over hours, this is exactly the range it lives in for most of its life.
Why a bigger window doesn’t fix it
The instinct, understandably, has been to treat this as a capacity problem and solve it with capacity. Every major lab has pushed context windows further, and it’s genuinely useful work, a bigger window means more room for legitimate task-relevant information.
But the Chroma results are explicit that a bigger window doesn’t fix degradation from irrelevant content, it just gives you more room to fit irrelevant content in. If distractors are the mechanism, then a bigger haystack doesn’t help you find the needle faster, it can make it slightly harder, because there’s more haystack for the model to attend across.
This is the point where I think the industry response has actually been genuinely good, and Anthropic in particular has been ahead of most of the field in naming and addressing this directly, just narrower in scope than the headline makes it sound.
What compaction does well, and where the next layer needs to go
Anthropic’s own guidance on this, published in September 2025, was one of the earliest clear, practitioner-facing treatments of exactly this problem, describing compaction as the practice of summarizing a conversation as it nears its context limit and starting a fresh window with that summary in place of the full history. It’s now a real, shipped feature in the Claude Platform SDK, not just a blog post idea, and it directly targets the failure mode that matters most for long-running agents: a session that would otherwise just keep growing until it breaks. (Anthropic, “Effective context engineering for AI agents”, Claude Platform Docs, context editing) For an agent that’s meant to run for hours or days without a human resetting it, having that handled automatically, rather than left to every team to build themselves, removes an entire category of failure that used to be a hard prerequisite just to keep a long session alive at all.
I want to be precise about what this covers, not because it falls short, but because it clarifies where the next piece of work sits. Compaction is triggered by token count, it fires when a conversation is approaching its limit, which is exactly the right trigger for the problem it’s solving: an agent that’s been running long enough to genuinely need more room. What it isn’t designed to catch is a window that’s, say, a third full and already carrying distractors, content that’s related but no longer useful. Nothing about compaction is evaluating relevance, only size, so a long-running agent that never approaches its token limit but is quietly accumulating stale tool output can still be degrading in the exact way Chroma’s research describes, even while compaction is working exactly as intended.
So compaction solves the running-out-of-room problem for long-running agents extremely well, and solves it in a way I think other teams should be looking at closely rather than reinventing. It’s a different problem, though, from the room-is-full-of-noise problem, and a long-running agent can hit the second one on day one of a run, long before it would ever trigger the first.
The layer that could sit on top
What would extend this further, in the direction Anthropic’s own framing already points, is something closer to continuous curation, a way of evaluating, at each step, whether something already in the context is still relevant to what the agent is doing now, and removing or deprioritizing it if it isn’t, independent of how full the window happens to be. For an agent that runs for days, that judgment needs to happen continuously across the entire run, not just at the moments the window happens to fill up.
That’s a meaningfully harder problem than triggering a summary at 90 percent capacity, and I don’t say that to diminish the compaction work, if anything it’s the reason compaction was the right thing to build first. It requires a live judgment about relevance, not just a token count, and it has to run cheaply enough to do this on every step of a long session without becoming the new bottleneck. I don’t think anyone has this built as a general, reliable layer yet. Retrieval-augmented generation gets at part of it, by only pulling in what seems relevant to begin with, but RAG has its own well-documented failure modes around retrieval quality and doesn’t touch content that’s already sitting in an active conversation.
I’ll say plainly what I’m not claiming, I’m not claiming compaction is poorly built or that Anthropic missed something obvious. It’s a well-scoped answer to a real problem, and one of the more useful pieces of infrastructure to come out of this whole space so far. I’m claiming there’s a second, narrower problem sitting right next to it, one that specifically matters for agents that don’t get the luxury of a human resetting their session, and that’s where I think the next layer of work has to happen.
Where this leaves things
Long context windows are a real and valuable capability. They are not, on their own, the same thing as an agent that knows what to do with a long history, and the data backs that up more precisely than I expected going into this. For an agent running once and returning an answer, none of this matters much. For an agent that’s meant to run continuously, compaction is genuinely good, necessary infrastructure for staying alive over a long session. It’s just not, on its own, infrastructure for staying sharp over one.
Next up: what happens when tools built for a quick call-and-return get used hundreds of times in a row, or looped between agents, and why that breaks in ways the original RPC model never had to account for.